Incident investigation
Cloudflare: why a new sandbox contained someone else's old files
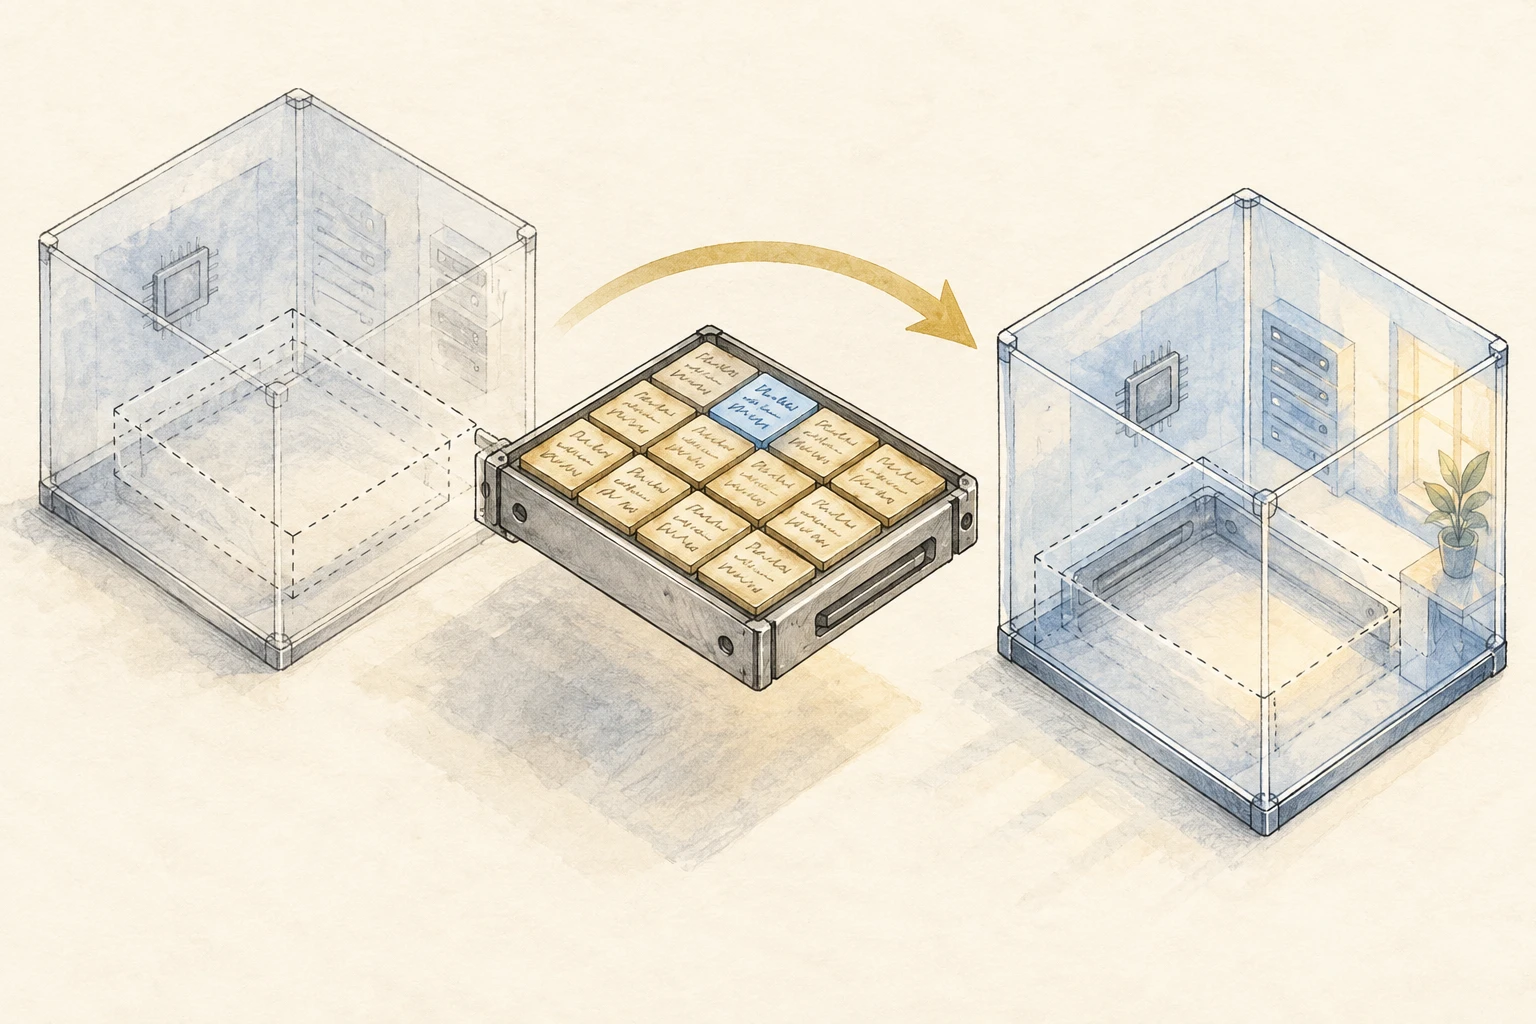
Cloudflare gave each container its own virtual machine, while recycled disk blocks brought in a previous user's data. A small write could make that residue readable. Repair required both zeroing newly allocated space and retiring disks and image caches that already retained it.
In this article
A fresh sandbox is supposed to be a disposable computer. You can compile an unfamiliar project or run agent-generated code inside it, then throw the environment away without touching anyone else's work. On September 24, Accomplish researcher Oren Yomtov disclosed that he had recovered other customers' file contents inside Cloudflare sandboxes. His account lists SQLite databases, Chromium profiles, .env files and credential files. It also identifies Browser Run as affected through the shared disk implementation.
The data came from the new environment's own disk. The joint Cloudflare and research-team report traces the failure to storage pools behind Containers and Sandboxes: blocks recycled between accounts were allocated without zeroing. A new disk could initially return nothing but zeros, then reveal a previous user's contents beside a small write. Why would writing one area change what could be read elsewhere? The answer lies in when the disk receives its physical storage.
1 The new disk gets its space when something writes
There are two layers to the disk. A program sees addresses it can read and write; the host decides which physical storage backs those addresses. Thin provisioning postpones physical allocation until a write needs it. A large-looking new disk can therefore consume very little real space. Linux's dm-thin connects the two layers through mappings, allowing multiple thin devices to obtain blocks from a common data pool.
That design puts a security decision at the point of allocation. Who used this space before, and what happened to its contents before the next owner received it? Removing an old mapping settles ownership in the map. If the pool later hands the same physical block to another disk, its bytes still need to be overwritten or cleared. A new name, identifier or filesystem cannot by itself establish that every underlying byte has changed.
In the affected deployment, each container ran in a separate Firecracker virtual machine with a writable root disk at /dev/vdc. Firecracker's device model helps explain the boundary: a guest reads and writes a block device provided to it, while the host supplies the backing resources. If that backing space already contains someone else's bytes, reading within the guest's own disk can return them. Taking control of another live virtual machine is unnecessary for this path.
The following source walk uses the public Linux v6.12 implementation to explain dm-thin behavior. Cloudflare has not disclosed its deployed kernel version, and this article includes no testing against the service. process_cell() first looks up the requested address. When a read has no mapping and no external origin supplying data, provision_block() fills the return buffer with zeros and completes the read. No physical block has been allocated.
The first read receives zeros filled in by the code, without touching a physical block. A later write obtains real storage and establishes a mapping. That is when old data can enter the new disk.
2 A small write gives the whole block a new owner
The researcher started an environment with a Workers Paid account and read and wrote raw bytes on /dev/vdc, choosing aligned locations in free space within the guest's ext4 filesystem. Residue need not belong to any normal file on the current disk. Listing its directories would miss this read path.
Cloudflare identifies the deployed thin-block size as 64 KiB and the pool option as skip_block_zeroing. An aligned 4 KiB write caused an entire block to be allocated. It replaced one sixteenth of the space, leaving 60 KiB potentially carrying earlier contents. That is the size left unwritten; what can actually be recovered depends on the block's history.
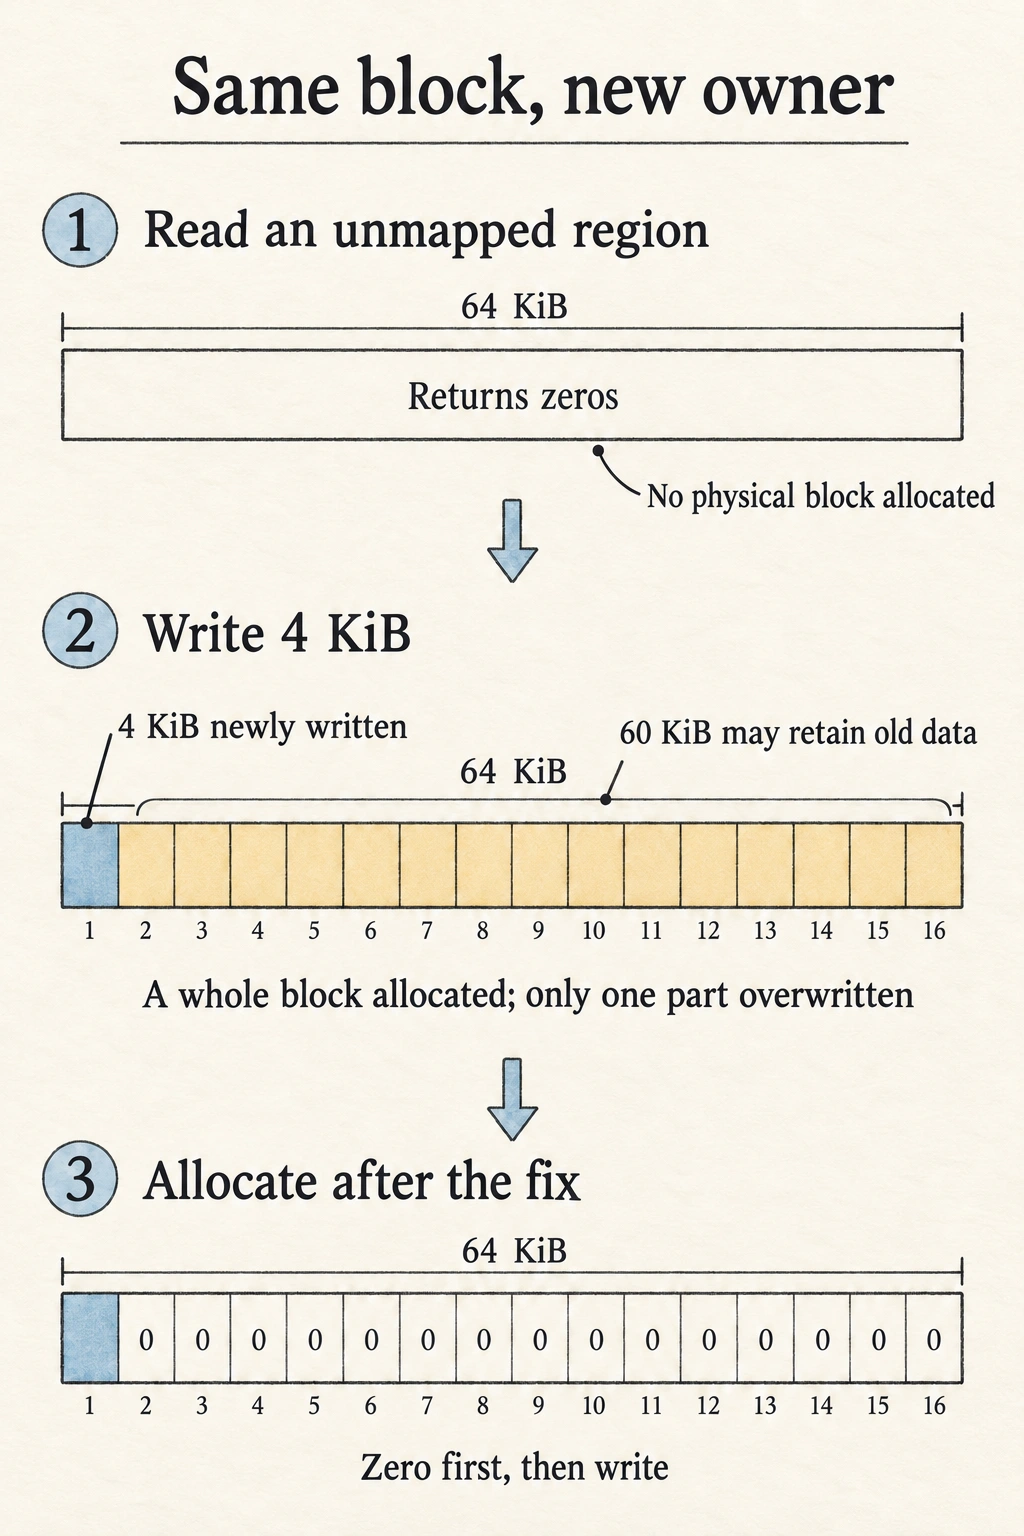
Linux v6.12 enables new-block zeroing by default. Parsing that option sets zero_new_blocks to false. In schedule_zero(), disabling zeroing leads straight to prepared-mapping processing. When enabled, a partial write must wait for zeroing.
Next, process_prepared_mapping() inserts the new association into the mapping tree. Later reads use that physical block directly, bypassing the earlier branch that returned zeros for an unmapped address. The sequence is now complete: the first read returns zeros, a write brings physical space into the current disk, and a second read can retrieve the portion that the write left untouched.
A full-block overwrite is a misleading test if used alone. Write fresh data to all 64 KiB and read it back, and only the fresh contents should appear. Even with zeroing enabled, the kernel can skip a separate clear when the write replaces the whole block. A test that distinguishes the two cases must leave some space unwritten. Checking only that the bytes you wrote come back misses the unexpected bytes elsewhere.
The researchers traced the residue with ext4 directory checksums. The ext4 documentation specifies a calculation involving the filesystem UUID, inode number, inode generation and directory contents. Using their own filesystem identity, none of 5,614 testable directory blocks matched. All 162 control blocks they deliberately created and deleted did match. Together, the results support the attribution of the residue to other filesystems.
3 The setting is repaired; existing disks keep their state
Enable zeroing and repeat the allocation, and the unwritten portion is cleared. An already mapped block, however, still follows its existing association. Consider a disk that obtained a residue-bearing block before the repair and simply reads it afterward. No new allocation occurs, so the new zeroing condition never participates.
Snapshots can extend the lifetime of those old mappings. An internal dm-thin snapshot initially shares data blocks with its source. The source commentary on copy-on-write describes two mapping trees pointing to the same data, with later writes separating them. Reads of shared blocks still use the existing physical addresses. A new instance created after the fix can therefore inherit a mapping established before it, if it starts from an older snapshot.
In this incident, cleanup also covered prepared dm-thin snapshots behind host-cached OCI image layers. Reusing image preparation had preserved the disk state created during that work. Cloudflare completed the zeroing rollout at 06:13 UTC on September 7 and the pre-mitigation cache cleanup at 15:03 UTC on September 19, retiring old container disks, restarting VMs and clearing host image caches. The two dates answer different questions: when new dirty allocations stopped, and when retained state that could be inherited was removed.
Operators of a similar platform can design an isolated test using their own marker data: an unmapped read, a partial write after release and reallocation, a full-block overwrite, and a new disk created from a pre-fix snapshot. The first three distinguish allocation from overwrite; the fourth checks whether old state propagates. Record the mappings and confirm that each reuse test receives the marked physical block. Receiving a different, clean block would miss the recycling defect. These proposed tests have not been run.
4 What users still need to know
As checked on October 2, Cloudflare says repair and cleanup are complete and customers need no configuration change or additional action. Its review of retained disk-I/O telemetry identified authorized research and engineering activity, with no evidence of other malicious exploitation. Public material does not provide a complete exposure window or a per-customer disclosure list. Establishing whether a particular company's file was read still requires records held by the provider.
The opportunity was limited to recycled space on the same host. Placement was controlled by the platform, and researchers could not select a customer or an active disk. For users, assessing consequences therefore starts with actual workloads: which tasks wrote databases, browser state or secrets into an affected environment? If a provider notification or internal evidence identifies a particular credential, its permissions, lifetime and use history guide revocation, replacement and investigation.
Agent workspaces can also put fewer secrets on disk. A credential used only to call an external API can stay in a controlled service outside the workspace that makes the request. Credentials needed by the task itself should have limited scope and lifetime. This reduces what a future residue leak could expose. Past reads still need the investigation described above, and the platform still needs to zero storage and remove retained state.
Sandbox evaluation should follow state beyond the end of a task. The VM process exits; physical blocks, image caches and snapshots can survive and pass to the next user. The check needs to follow that handoff, beyond the new instance's first read of an empty disk.